One trait to implement
Plug in a local engine by implementing LlmBackend, which runs on a
blocking thread with no async required, or a hosted chat API with
ChatBackend. Orion owns the async orchestration.
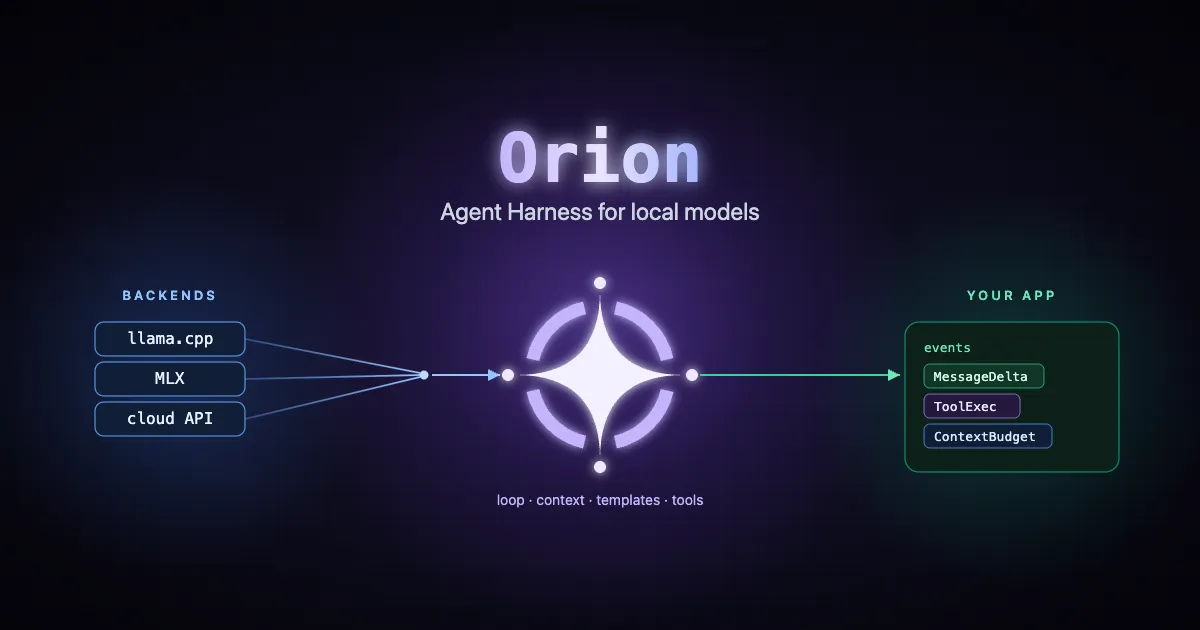
Agent harness for local LLM inference. Backend-agnostic - bring your own model runtime (llama.cpp, MLX, cloud APIs, anything).
Orion handles the conversation loop so you don’t have to: context
management, token budgets, streaming events, chat formatting, and an automatic
tool-execution loop. You implement one backend trait for your inference
engine - LlmBackend for a local engine, ChatBackend for a hosted chat API -
and Orion handles everything above it.
User sends "Hello"  → Agent.prompt("Hello")    → Context pipeline (prune old messages to fit token budget)      → Format prompt (ChatML template + tool definitions)        → LlmBackend.generate() (streams tokens one by one)          → AgentEvent stream (your UI subscribes here)            → If the model called tools: run them, append results, loop back              → Done (model returns a tool-free answer)
Agent.inbox() reaches the agent mid-run (read before every model call),and Agent.resume() carries a conversation on without new user text.One trait to implement
Plug in a local engine by implementing LlmBackend, which runs on a
blocking thread with no async required, or a hosted chat API with
ChatBackend. Orion owns the async orchestration.
Streaming events
Subscribe to an AgentEvent stream for tokens, tool execution, and
context-budget updates - everything a reactive UI needs.
Automatic tool loop
The agent parses tool calls, runs your tools, feeds results back, and loops until the model returns a final answer.
Work that outlasts a turn
Tools can hand back a pending result and deliver it later through the inbox, a run can be resumed after a restart, and a tool can run a child agent whose events stream into the parent’s.
Context management
Prune to a token budget with a sliding window or summarization, pin messages that must survive, and format with the right chat template.